
Source: OS System
Introduction
How do you handle multiple data types in AI? Traditional language models process only text, creating limitations when dealing with images, audio, or video content. Meanwhile, separate models for each modality create fragmented systems that can’t understand relationships across different data types. That’s why Multi-Modal Large Language Models (MLLMs) have emerged as a revolutionary solution in modern AI pipelines, striking a balance between specialized processing and unified understanding.
Multi-Modal Large Language Models (MLLMs)
So far, you may have explored GPT-4 and Gemini, the two widely adopted multimodal systems. But there’s a deeper understanding needed: Multi-Modal LLMs. Developed by leading AI companies and introduced through groundbreaking research, MLLMs take a unified view of data processing, integrating text, images, audio, and video into cohesive frameworks. This approach proves especially valuable for applications requiring comprehensive understanding (like medical diagnosis or autonomous systems), while also supporting robust cross-modal reasoning and real-time interaction.
In this article, we’ll cover the following:
- Dive into the origins and core principles of Multi-Modal LLMs
- Explain how they differ from (and often complement) traditional LLMs and specialized models
- Demonstrate their main architectural components, the fusion modules and cross-attention mechanisms and available training strategies
- Provide practical examples of how to build and use MLLMs, with tips on multimodal training and deployment scenarios
- Offer comparative analysis of leading models like GPT-4 Vision and Google Gemini
By the end, you’ll see how Multi-Modal LLMs can help you process diverse data types in a unified, intelligent manner, and why they’re widely considered a new frontier in artificial intelligence.
Visual Overview: Understanding Multimodal AI Architecture
Before diving deep into Multi-Modal LLMs, let’s visualize how different AI architectures handle multiple data types:
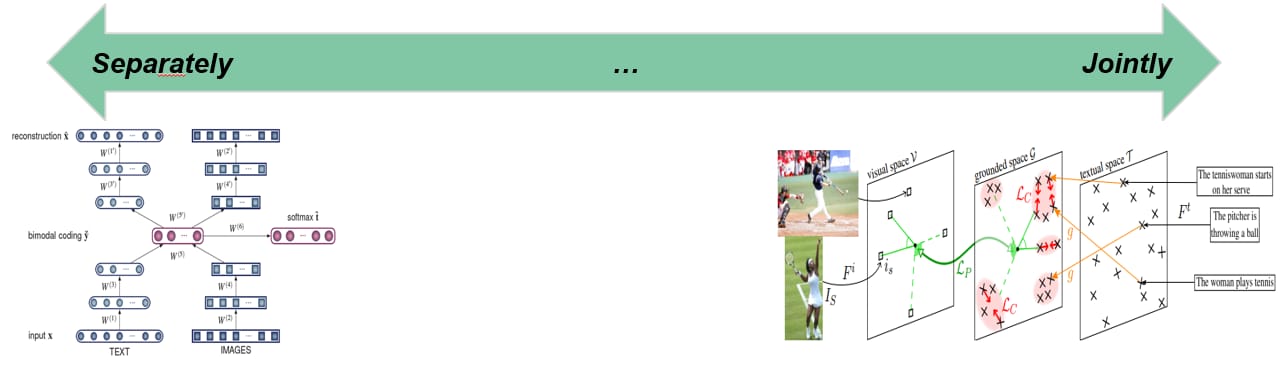
Source: Multimodal Deep Learning by Matthias Aßenmacher
Historical Perspective & Core Principles
Origins
Multi-Modal LLMs emerged from Google’s and OpenAI’s efforts to handle diverse data types beyond text. Traditional AI systems that rely on separate models for each modality create fragmented understanding and miss crucial cross-modal relationships. Research teams proposed unified approaches that process multiple modalities simultaneously, packaged in systems like “GPT-4 Vision” and “Gemini,” which quickly gained traction within AI research and commercial applications.
Once these systems were released, the broader AI community adopted them for a wide variety of tasks, including visual question answering, multimodal generation, and real-time interaction. The key design philosophy is that all input data including text, images, audio, and video should be viewed as unified representations, with cross-modal understanding baked into the model architecture.
Key Innovations
- Unified Processing: MLLMs avoid separate processing pipelines. Instead, they introduce fusion modules that combine information from different modalities into joint representations.
- Cross-Attention Mechanisms: Instead of independent processing (traditional approach) or simple concatenation, MLLMs use attention mechanisms that allow each modality to attend to relevant information from other modalities.
- Multimodal Training: A concept allowing simultaneous learning across modalities, thus improving the robustness of AI models to diverse input combinations and real-world scenarios.
Why It Matters
By lifting constraints about single-modality processing, Multi-Modal LLMs become ideal for real-world applications that require comprehensive understanding. They also centralize the multimodal learning process in a single framework, letting you choose between retrofitted or native approaches, experiment with fusion strategies, or adopt cross-modal training features.
Inside Multi-Modal LLMs: Architecture Components
Input Modules (Modality-Specific Encoders)
The input modules are the foundation of multimodal processing. Here’s how they work:
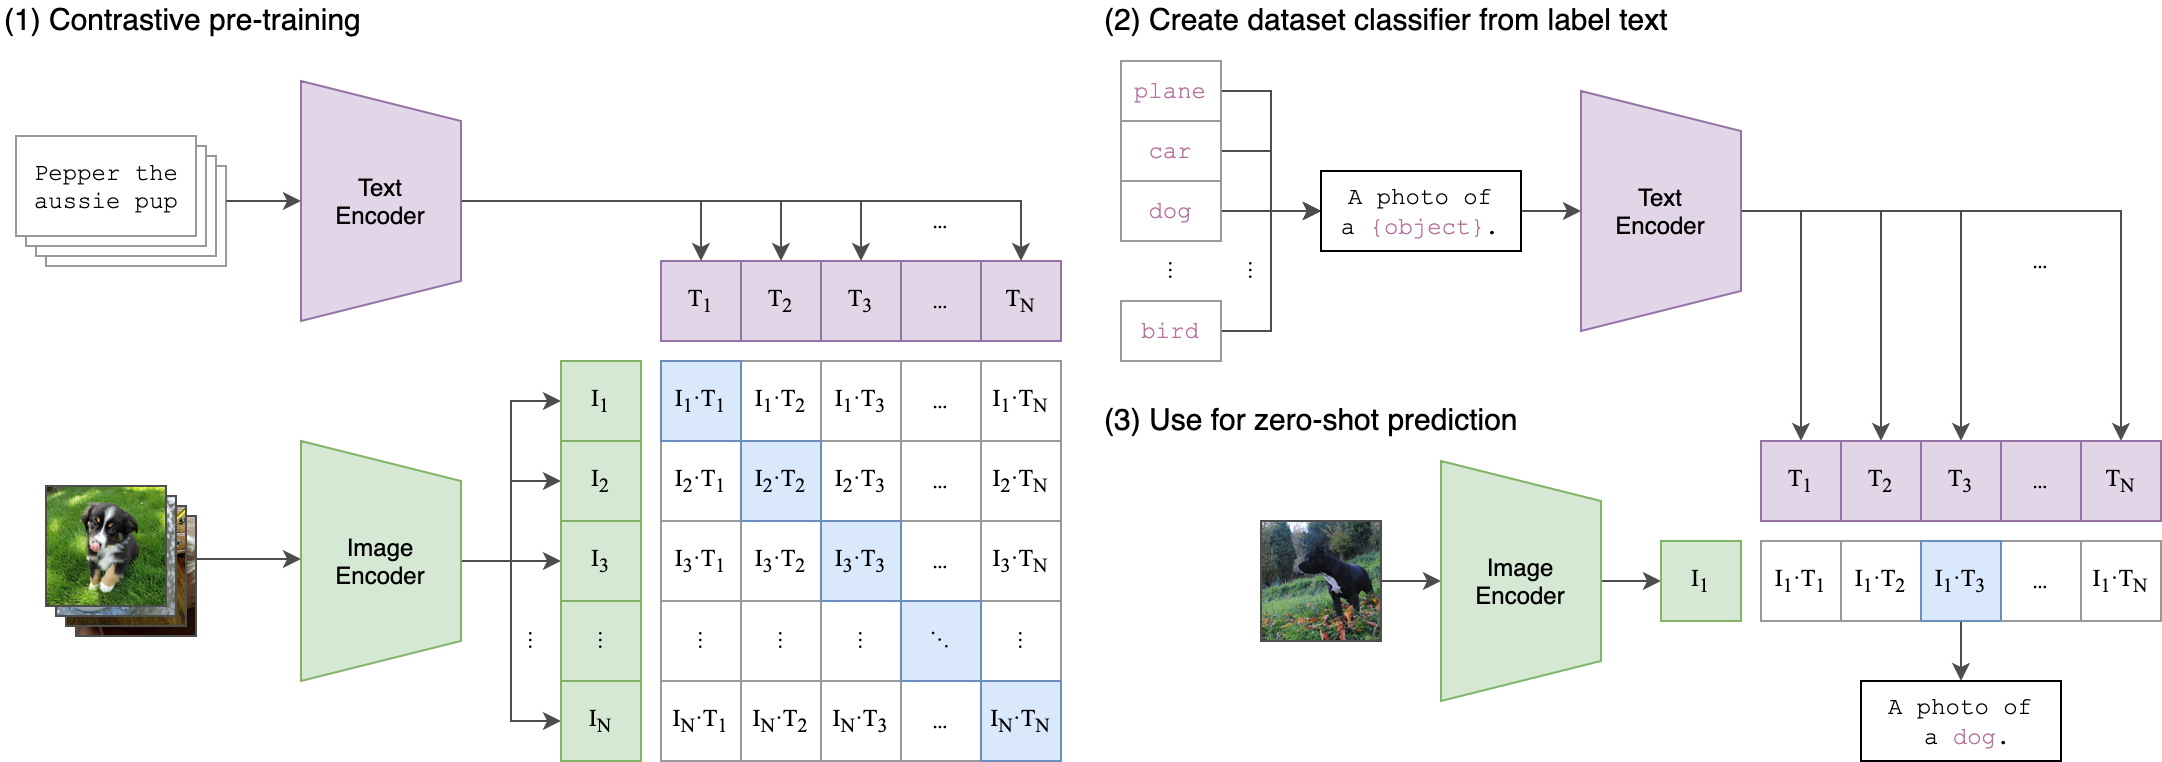
Vision Encoders: Modern MLLMs predominantly utilize CLIP-based encoders or Vision Transformers (ViT) that process images into patch embeddings.
Text Encoders: Large pre-trained transformers provide foundational language understanding capabilities, often kept frozen during multimodal training.
Audio Encoders: Specialized neural networks encode audio waveforms into structured representations that can be integrated with other modalities.
Key Difference from Traditional Approaches: Unlike separate models which process each modality independently, MLLMs design encoders specifically for cross-modal integration, ensuring compatibility and optimal information flow between different data types.
Mathematical Representation: The encoding process transforms raw sensory data into structured representations:
Source: OpenAI
Fusion Module
Interestingly, MLLMs also support various fusion strategies. If your application requires different integration approaches, you can choose from multiple fusion methods while still benefiting from:
- Cross-attention mechanisms that enable selective focus across modalities
- A unified processing environment for different data types
This flexibility makes MLLMs a one-stop solution for many multimodal strategies.
Cross-Attention Mechanisms
One unique feature is Cross-Attention, introduced in modern transformer architectures. During processing, MLLMs can dynamically attend to relevant information across modalities, teaching the model to handle complex relationships more gracefully. This technique helps prevent information silos and improves model understanding.
How it works: Instead of processing each modality independently, MLLMs use attention mechanisms where queries from one modality attend to keys and values from another modality. This creates rich cross-modal understanding that goes beyond simple concatenation.
Comparing Multi-Modal LLMs with Traditional Approaches
Processing Workflow
- Traditional LLMs: Process only text data, requiring separate models for other modalities
- Specialized Models: Handle single modalities with high performance but lack cross-modal understanding
- Multi-Modal LLMs: Process multiple modalities simultaneously through unified architectures like an integrated approach to traditional fragmented systems
Data Integration & Understanding
Typically, traditional approaches assume you’ve processed each modality separately.
Multi-Modal LLMs treat all data types as unified inputs in a single processing stream, enabling them to handle complex relationships between modalities. This is also beneficial for real-world applications with diverse data requirements.
Performance Consistency
Traditional approaches can produce inconsistent results when modalities conflict or provide contradictory information.
Multi-Modal LLMs can yield coherent understanding across modalities, but that’s often a feature (when cross-attention is properly implemented).
In practical usage, the differences become more apparent in complex applications or real-time scenarios.
Real-World Usage
- OpenAI uses Multi-Modal LLMs extensively in GPT-4 Vision for visual understanding and reasoning
- Many AI companies (Google, Anthropic, etc.) provide Multi-Modal LLM integrations, reflecting their growing importance
Hands-On with Multi-Modal LLMs
Building a Simple Multi-Modal Model
import torch
import torch.nn as nn
from transformers import CLIPModel, AutoTokenizer, AutoModel

class SimpleMultiModalLLM(nn.Module):
    """
    A simple implementation of a Multi-Modal Large Language Model
    that combines CLIP for vision understanding with a language model.
    """
    def __init__(self, clip_model_name='openai/clip-vit-base-patch32',
                 llm_model_name='microsoft/phi-2'):
        super().__init__()

        # Load pre-trained models
        self.clip_model = CLIPModel.from_pretrained(clip_model_name)
        self.text_model = AutoModel.from_pretrained(llm_model_name)

        # Projection layers to align different modality dimensions
        clip_dim = self.clip_model.config.projection_dim
        llm_dim = self.text_model.config.hidden_size

        # Linear projection to map vision features to text space
        self.visual_projection = nn.Linear(clip_dim, llm_dim)

        # Transformer layer for cross-modal fusion
        self.fusion_layer = nn.TransformerDecoderLayer(
            d_model=llm_dim,
            nhead=8,
            dim_feedforward=2048,
            dropout=0.1
        )

        # Output projection for final predictions
        self.output_projection = nn.Linear(llm_dim, llm_dim)

    def forward(self, images, input_ids, attention_mask):
        # Encode images using CLIP vision encoder
        vision_outputs = self.clip_model.vision_model(pixel_values=images)
        vision_features = vision_outputs.last_hidden_state

        # Project vision features to match text dimensions
        vision_projected = self.visual_projection(vision_features)

        # Encode text using language model
        text_outputs = self.text_model(
            input_ids=input_ids,
            attention_mask=attention_mask
        )
        text_features = text_outputs.last_hidden_state

        # Fuse modalities using cross-attention
        fused_features = self.fusion_layer(
            tgt=text_features,
            memory=vision_projected
        )

        # Apply output projection for final processing
        output_features = self.output_projection(fused_features)

return output_featuresThe model_type can be set to different fusion strategies if you want alternative approaches instead of cross-attention.
dimension_alignment helps define how different modality representations are mapped to a common space.
Training/Inference
# Initialize the model
model = SimpleMultiModalLLM()

# Example usage
images = torch.randn(1, 3, 224, 224)  # Batch of images
input_ids = torch.tensor([[1, 2, 3, 4, 5]])  # Tokenized text
attention_mask = torch.tensor([[1, 1, 1, 1, 1]])

# Forward pass
outputs = model(images, input_ids, attention_mask)

print("Fused features shape:", outputs.shape)
print("Model successfully processes multimodal inputs")Notice how different modalities are processed through unified attention mechanisms.
Potential Experiments
- Tweak fusion_layer parameters to see how cross-modal understanding changes
- Try different vision encoders vs. different language models
- Test on multiple modalities or specialized domain data
Using Multi-Modal LLMs in your projects often involves just a few lines of code, especially if you rely on pre-trained models or established frameworks.
Domain & Multimodal Considerations
Multimodal Scenarios
Many modern applications (e.g., autonomous vehicles, medical AI) rely on Multi-Modal LLMs because:
- Unified Processing: Perfect for applications that require understanding across multiple data types
- Cross-Modal Reasoning: You can train a joint understanding system that handles relationships between modalities
However, unified multimodal processing can sometimes lead to computational overhead if the fusion mechanisms are not optimized for specific use cases.
Domain Shifts
General-purpose multimodal models like GPT-4 might not contain domain-specific multimodal patterns (medical imaging, scientific data). If you plan to process or generate content in a specialized area, consider:
- Domain Fine-Tuning: Additional training on domain-specific multimodal data (e.g., medical images with reports)
- Cross-Modal Regularization: Let the model see multiple modality combinations, making it more resilient to domain variations
Multi-Modal LLMs can handle new modality combinations by leveraging cross-attention, but domain adaptation typically yields better performance and more coherent multimodal understanding.
Strengths, Pitfalls, and Best Practices
Strengths
- Unified Understanding: Doesn’t assume separate processing pipelines. Suitable for any multimodal task
- Cross-Attention: Often leads to robust multimodal understanding that captures relationships between modalities
- Real-Time Processing: A unique advantage for interactive applications and dynamic environments
- Single Framework: Can handle both text-image and audio-video combinations versatile for different research or production needs
Pitfalls
- Computational Complexity: Processing multiple modalities simultaneously can be memory-intensive for large-scale applications, especially with high-resolution inputs
- Cross-Modal Alignment: Ensuring semantic consistency across different modalities can be challenging and may require careful training strategies
- Over/Under Integration: If fusion mechanisms are too simple, you might miss important cross-modal relationships. If too complex, you might overfit to specific modality combinations
Best Practices
- Tune Fusion Architecture: Common approaches range from simple concatenation to complex attention mechanisms, depending on task complexity
- Evaluate Cross-Modal Performance: Test your model on tasks that require understanding relationships between modalities
- Consider Computational Efficiency: Especially if your application requires real-time processing or deployment on resource-constrained devices
- Leverage Pre-trained Models: Multi-Modal LLMs offer robust pre-trained components for quick experimentation without training from scratch
Conclusion & Future Directions
Multi-Modal Large Language Models (MLLMs) mark a major shift in AI, moving from text-only systems to models that can jointly reason over text, images (and increasingly audio/video) for more natural, comprehensive interactions. Architectures such as cross-attention enable unified processing and integrated multimodal understanding, overcoming many limitations of single-modality pipelines especially in high-impact areas like autonomous systems, medical AI, and creative content generation.
That said, there’s no one-size-fits-all choice. Traditional LLMs can be simpler to deploy, and specialized multimodal stacks can integrate cleanly with existing frameworks. But MLLMs tend to shine when you need complex reasoning across modalities, real-time interaction, or a single model that can be trained and extended across diverse data types. The comparison between GPT-4 Vision and Google Gemini highlights two valid philosophies – retrofitted multimodality vs. native multimodality, each bringing different trade-offs in performance, flexibility, and system design.
Looking ahead, multimodal AI is evolving quickly: researchers are exploring more efficient architectures and even token-free or continuous representations that may reduce reliance on traditional tokenization. As these models become more capable and computationally efficient, they’re likely to be embedded more deeply into everyday products and specialized workflows.
The journey toward truly multimodal artificial intelligence has only just begun, and the potential applications are limited only by our imagination and commitment to responsible development. As these technologies mature, they will undoubtedly reshape industries, enhance human capabilities, and open new frontiers in human-computer interaction.
Video
- Advanced Video: Cross-Modal Attention in Practice: This video by Google breaks down Med-PaLM 2, a LLM designed for use in the medical field. It includes a deep dive into cross-modal attention and its practical applications. (Runtime: ~3 mins)

- Understanding Multi-Modal LLMs: Greg Brockman, President and Co-Founder of OpenAI, showcases GPT-4 and its abilities. The video contains a comprehensive visual explanation of Multi-Modal LLMs. (Runtime: ~24 mins)

References & Further Reading
Research Papers
- Flamingo: a Visual Language Model for Few-Shot Learning
- BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models
- Gemini: A Family of Highly Capable Multimodal Models
- GPT-4 Technical Report
- An Image is Worth 16×16 Words: Transformers for Image Recognition at Scale
- Learning Transferable Visual Models From Natural Language Supervision (CLIP)
Interactive Demos and Tools
- Google AI Studio – Gemini Playground
- OpenAI GPT-4 Vision API
- BLIP-2 Interactive Demo
- BLIP Model Repository
- Gemini Multimodal Live API
Educational Resources
- Multimodal Deep Learning Course (Coursera)
- Hugging Face Multimodal Transformers Course
- Understanding Multimodal LLMs (Sebastian Raschka)
- DeepLearning.AI Courses
Community and Support
- Hugging Face Discord Community
- Stack Overflow – Multimodal ML
- r/MachineLearning Reddit Community
- GitHub Multimodal Learning Projects
Technical Documentation
- PyTorch Multimodal Tutorials
- TensorFlow Vision and Language Tutorials
- Transformers CLIP Documentation
- Gemini API Documentation